
PDF Text Extractor API
Precision text and metadata retrieval for document automation.
A powerful REST API for extracting structured text and metadata from PDF files using optimised hybrid methods. Supporting page range selection and layout-aware processing.
Everything you need, nothing you don't
Multi-Method
Choose between PyPDF2 for speed or pdfplumber for complex layout accuracy
Page Ranges
Precise extraction from specific pages or ranges (e.g., 1-3, 5, 10)
Metadata Sync
Automatically extract title, author, and creation metadata alongside text
Batch Processing
Optimised pipeline for handling multiple PDFs simultaneously
Hybrid Extraction Engine
Choose the right tool for the job. Our API integrates PyPDF2 for ultra-fast extraction of standard text documents and pdfplumber for complex layouts, forms, and table-heavy PDFs where spatial positioning is critical.

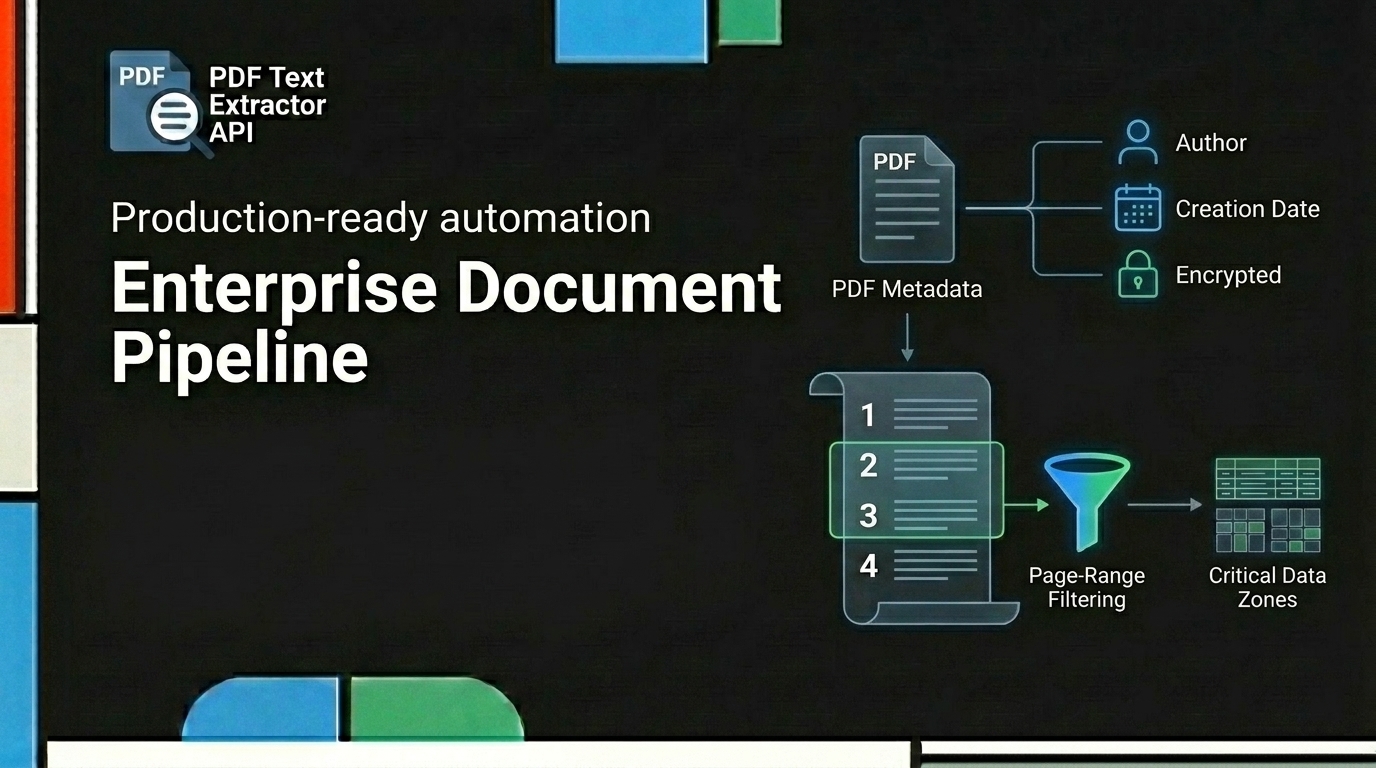
Enterprise Document Pipeline
Beyond raw text, your application gains access to rich document metadata such as author, creation date, and encrypted status. Use our page-range filtering to reduce egress costs and focus extraction on critical data zones.
Ready to try PDF Text Extractor API?
A powerful REST API for extracting structured text and metadata from PDF files using optimised hybrid methods. Supporting page range selection and layout-aware processing.